Google’s 2026 Environmental Report overview reported that its electricity demand rose 37 percent over the year while operational emissions fell two percent. The company’s account is a useful counterweight to a common assumption in the AI debate: that improved efficiency should necessarily produce lower total electricity use. Efficiency and total demand measure different things, and they can move in different directions.
Autonomous AI makes the distinction more consequential. A service may become cheaper at one familiar task while customers begin using it for longer, more demanding work. More efficient inference can help make those new uses affordable. The result may be better economics per completed job and a larger electricity bill across the whole system.
The denominator needs to stay visible
An efficiency claim is incomplete without saying what is being measured. Energy per token, per request and per accepted task are different metrics. A model that produces shorter answers may look efficient per request while leaving more work for the user. An agent that performs extra checks may consume more tokens but deliver a result requiring less correction.
For a meaningful comparison, the task and acceptance threshold should remain fixed. The operator can then measure whether the system needs fewer resources to achieve the same result. Separately, it can report whether customers are asking for more results or moving to more demanding tasks. Combining those effects makes it difficult to identify what the technology has actually improved.
The workload mix is changing
The IEA’s 2026 update identifies uptake, efficiency and changing AI use cases as distinct drivers of electricity demand. Its analysis treats reasoning and agentic work differently from a simple text query. That is the right conceptual separation: an hour-long workflow should not be evaluated as if it were merely another short message in a chatbot.
This does not establish that every agent is energy-intensive or that every long run is useful. Some automation can avoid repeated human work or replace a more resource-intensive process. The relevant comparison depends on the task it actually replaces. A system doing unnecessary work can increase consumption without creating corresponding value, even if the underlying hardware is efficient.
Benchmark improvement is not a demand forecast
MLCommons’ April 2026 release updated several inference tests to reflect contemporary workloads. Such benchmarks help show what systems can achieve under defined conditions. They do not determine how often people will use those systems, how long their tasks will become or how providers will choose to allocate newly available capacity.
A company can therefore report strong performance gains and still plan to buy more hardware. The additional capacity may serve more customers, support different models or shorten waiting times. To judge the decision, an investor needs the connection between infrastructure spending and useful demand. A benchmark result alone cannot supply it.
Flexibility addresses timing rather than the whole total
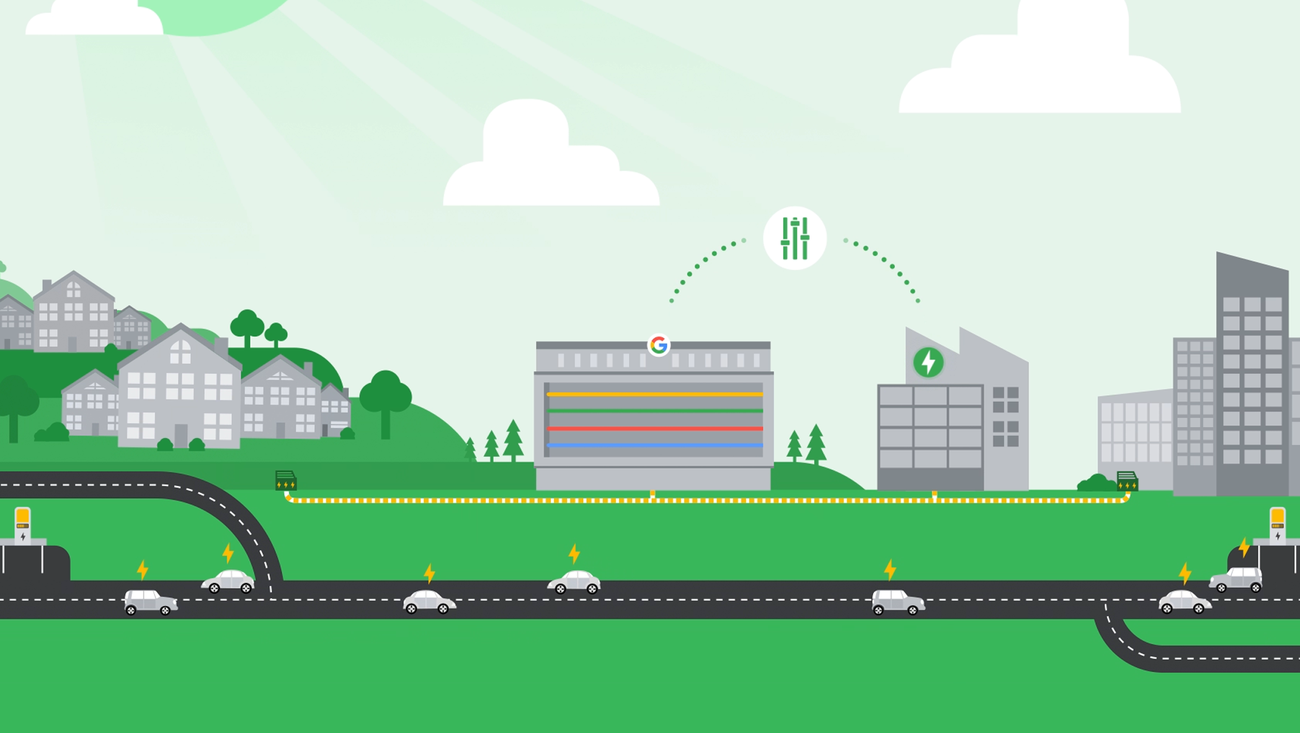
Google’s explanation of flexible data-center demand describes moving or reducing some work during particular periods. That can help a power system accommodate computing growth. It should not automatically be counted as an equivalent reduction in annual energy use, because deferred work may still be performed later.
The distinction matters for public reporting. Reduced peak demand, reduced total electricity, lower emissions and lower customer cost are separate outcomes. A program can improve one without improving all of them. Reporting the measures separately allows readers to understand both the achievement and its limits, rather than treating every improvement as interchangeable environmental progress.
A useful scorecard would show both scales
At the task level, the operator should report the energy and computing cost of a defined accepted outcome. At the service level, it should report total demand and explain changes in user numbers, workload mix and capacity. At the facility level, location and timing matter because the same annual consumption can impose different requirements on different power systems.
Those measures would also make waste easier to identify. Repeated failed tool calls, abandoned training runs and unnecessary generation consume resources without necessarily improving the product. Efficiency work can target them directly. The objective is not to make every job as small as possible, but to make resource use proportionate to a useful result.
The report’s renewable-energy matching claim concerns energy procurement accounting, while the electricity-growth figure concerns demand. Both can be meaningful without describing the same physical event. Buying an amount of renewable electricity equal to annual consumption is not, by itself, a statement that every facility draws carbon-free power at every hour. A clear account should retain the company’s reporting boundary and avoid converting one metric into another. That is especially relevant when an autonomous service spans multiple regions: an annual corporate figure does not automatically describe the conditions at the particular location running a customer’s task.
Google’s reported figures do not resolve the environmental debate around AI, and company-wide electricity use cannot be assigned entirely to one product category. They do show why the debate needs more than a single efficiency claim. As autonomy expands the amount of work software can attempt, the industry should explain both how economically it performs each task and how much work it is choosing to perform in total.
Sources & evidence
This archive preserves its original editorial date. Sources describe the events and announcements discussed; they do not establish today’s status.